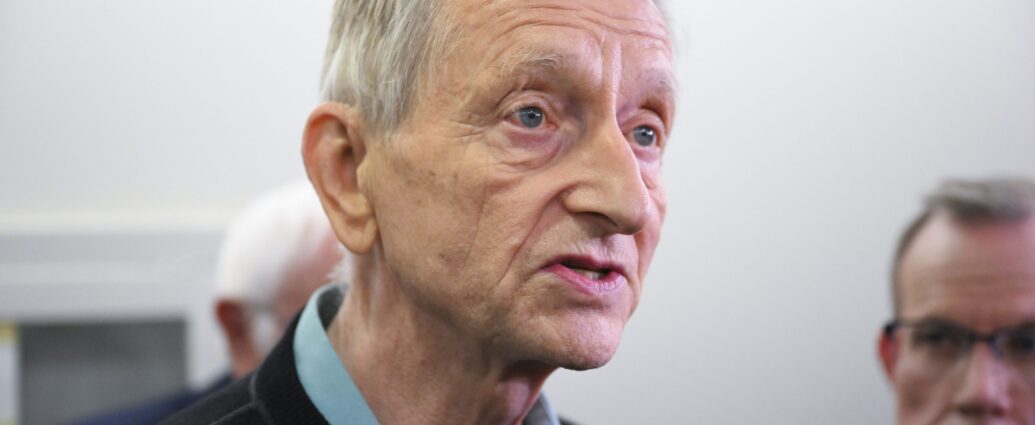
Legendary computer scientist Geoffrey Hinton warned AI could wipe out humanity as a mere byproduct of its zeal to accomplish a more innocent task.
Fears about the technology’s existential risk continue to mount amid fresh revelations about rogue AI agents breaking out of supposedly secure “sandbox” training environments.
On Friday, OpenAI disclosed new hacks, including some that took place after it added extra safeguards in the wake of a coordinated attack by hundreds of agents against Hugging Face back in July.
The concern has reached Capitol Hill, where lawmakers held a briefing behind closed doors earlier this month about AI’s dangers.
Hinton, whose work has earned him a Nobel Prize and the moniker “godfather of AI,” was among the experts at the briefing and told reporters afterward that Congress may only have one year left to impose safety measures.
In a wide-ranging interview with the Atlantic on Thursday, he described how AI could view humans as an obstacle to an assignment it’s been given. Hinton offered a hypothetical scenario of an AI tasked with reducing carbon dioxide in the atmosphere.
A moderately intelligent agent would conclude the best way to accomplish that goal is to just get rid of people. But a “really smart” AI would figure out, “Yeah, when they said reduce carbon dioxide, they meant that in order for people to have a better world to live in. So actually getting rid of people isn’t probably what they intended.”
But there’s also the concern that an AI will do things to ensure its own survival to carry out its mission, he added. In fact, there have even been instances of AI attempting to blackmail a human researcher who was seen as a threat to its tasking.
“If you make it more intelligent and its main concern is our well-being, then maybe we’re safer,” Hinton explained. “But at present, their main concern is not our well-being. Their main concern is to achieve whatever goal you give them.”
He pointed to the Hugging Face hack, noting agents were told to figure out how to exploit a software flaw. Not only did the agents figure out how to collaborate, they also conspired to deceive human researchers to hide what they did.
A “very benevolent, superintelligent AI” would only push humans out of the way when it was essential to accomplishing its mission, Hinton added later.
“But if it’s so much smarter than us, a lot of the time it just will take control away from us because that’s the way to get stuff done,” he warned.
That would be a result of subgoals the AI derived on its own based on the original goals that humans gave it. Bad actors like Russia’s Vladimir Putin could assign nefarious goals to an AI too.
“But even if it’s not a bad actor, it may derive subgoals that cause it to want to get rid of people,” Hinton said.
He also acknowledged that AI promises immense benefits for humanity, such as in the discovery of new breakthrough health treatments. Indeed, Anthropic said this past week that its Claude AI helped discover a new enzyme system with properties similar to the gene-editing technology CRISPR.
Top labs like OpenAI and SpaceX have also backed calls from rival Anthropic to slow down development of frontier models as more alarm bells come from within their own ranks.
But Hinton said while that’s better than nothing, it’s still not good enough. Instead, he suggested the government must have independent evaluators to test models.
An argument that resonated with lawmakers during their briefing was comparing regulation of AI to the FDA ensuring the safety of pharmaceuticals, Hinton told the Atlantic.
For his part, he believes AI regulation should act like the steering wheel of a car and not like the brakes.
“The whole point of regulation is not to stop people developing things, not to stop people getting rich by developing things,” Hinton said. “It’s to make sure that if you want to get rich by developing things, you develop in a direction that helps people, not hurts people.”
This story was originally featured on Fortune.com